Abstract
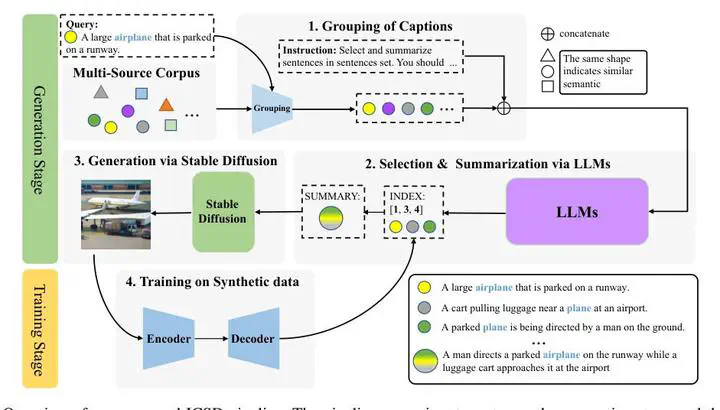
Image captioning requires numerous annotated image-text pairs, resulting in substantial annotation costs. Recently, large models (e.g. diffusion models and large language models) have excelled in producing high-quality images and text. This potential can be harnessed to create synthetic image-text pairs for training captioning models. Synthetic data can improve cost and time efficiency in data collection, allow for customization to specific domains, bootstrap generalization capability for zero-shot performance, and circumvent privacy concerns associated with real-world data. However, existing methods struggle to attain satisfactory performance solely through synthetic data. We identify the issue as generated images from simple descriptions mostly capture a solitary perspective with limited context, failing to align with the intricate scenes prevalent in real-world imagery. To tackle this, we present an innovative pipeline that introduces multi-context data generation. Beginning with an initial text corpus, our approach employs a large language model to extract multiple sentences portraying the same scene from diverse viewpoints. These sentences are then condensed into a single sentence with multiple contexts. Subsequently, we generate intricate images using the condensed captions through diffusion models. Our model is exclusively trained on synthetic image-text pairs crafted through this process. The effectiveness of our pipeline is validated through experimental results in both the in-domain and cross-domain settings, where it achieves state-of-the-art performance on well-known datasets such as MSCOCO, Flickr30k, and NoCaps.
本文提出一种基于多上下文合成数据的图像描述生成方法(ICSD)。针对现有合成数据仅能生成单一视角、上下文有限的问题,利用大语言模型从语料中提取同一场景的多视角描述并压缩为多上下文句子,再通过扩散模型生成复杂图像,仅用合成图像-文本对训练描述模型。在MSCOCO、Flickr30k和NoCaps等数据集上取得领先性能。