Microcinema: A divide-and-conquer approach for text-to-video generation
Abstract
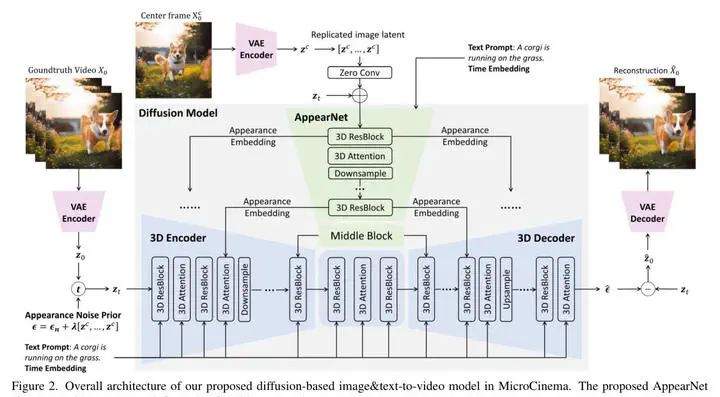
We present MicroCinema, a straightforward yet effective framework for high-quality and coherent text-to-video generation. Unlike existing approaches that align text prompts with video directly, MicroCinema introduces a Divide-and-Conquer strategy which divides the text-to-video into a two-stage process: text-to-image generation and image&text-to-video generation. This strategy offers two significant advantages. a) It allows us to take full advantage of the recent advances in text-to-image models, such as Stable Diffusion, Midjourney, and DALLE, to generate photorealistic and highly detailed images. b) Leveraging the generated image, the model can allocate less focus to fine-grained appearance details, prioritizing the efficient learning of motion dynamics. To implement this strategy effectively, we introduce two core designs. First, we propose the Appearance Injection Network, enhancing the preservation of the …
本文提出 MicroCinema,一种简洁而有效的文本生成视频框架。它采用分而治之策略,将任务分解为文本生成图像和图像与文本联合生成视频两个阶段,从而充分利用现有文本到图像模型的强大能力,生成逼真且细节丰富的图像,并让视频模型更专注于运动动态的学习。为高效实现该策略,文章设计了外观注入网络和外观噪声先验,以增强外观保持和视频连贯性,在多个基准上取得了优越性能。